Describe Features of Structured Data (DP-900 Exam Prep)

This post is a part of the DP-900: Microsoft Azure Data Fundamentals Exam Prep Hub. 
This topic falls under these sections:
Describe core data concepts (25–30%)
--> Describe ways to represent data
--> Describe features of structured data


Note that there are 10 practice questions (with answers and explanations) for each section to help you solidify your knowledge of the material. Also, there are 2 practice tests with 60 questions each available on the hub below the exam topics section.

Introduction

In the DP-900 exam, you’ll need to understand what structured data is, how it’s organized, and why its characteristics matter in the context of data storage, querying, and analytics.


What Is Structured Data?

Structured data refers to information that is organized in a well-defined format and schema, typically into tables with rows and columns. Each row represents a record (an instance of an entity), and each column represents an attribute of that entity — with a specific data type (like integer, string, date). Because the structure is defined up-front, systems know exactly how to store, validate, and query the data.

In practical terms, structured data is the type of data you find in:

  • Relational databases (e.g., Azure SQL Database)
  • Spreadsheets (e.g., Excel)
  • Data warehouses

In spreadsheets for example, each row is a record (e.g., a customer, an employee, a sale), and each column is a specific attribute (e.g., customer name, hire date, transaction amount). The schema tells the system exactly how the data is arranged. This predictably organized format makes structured data highly efficient for storage, retrieval, and analysis.


Key Features of Structured Data

1. Predefined Schema

Structured data has a fixed schema — a blueprint that defines how data is organized before it is stored or queried.

  • Every table has a set number of columns.
  • Each column has a defined name and data type (such as integer, decimal, date/time, text).
  • Attempts to insert data that does not conform to the schema are typically rejected.

Example:
An “Employee” table might have columns:
| EmployeeID (int) | Name (varchar) | HireDate (date) | Email (varchar) | IsActive (boolean) |

The database enforces rules that each column only accepts (and contains) compatible values. For example, the HireDate column, which has a “date” datatype, would not allow an entry of the employee’s job title (which is of the varchar or string datatype).


2. Tabular Organization

Structured data is most often stored in tables – and a table is made up of rows and columns:

  • Rows represent individual records (e.g., a customer, a sale, an order).
  • Columns represent data attributes (e.g., customer name, transaction amount, order date).

This row/column model is familiar from relational databases and spreadsheets. This tabular layout makes the data predictable, easy to view, understand, and ingest into analytical tools.


3. Strong Data Typing

Each column has a specific datatype and validation rules, such as:

  • Integer
  • String or text
  • Date/time
  • Decimal or numeric
  • Boolean

This data typing, which prevents invalid values from being stored, helps maintain data integrity, reduce errors, and ensure consistent interpretation of values. For example:

  • A “DateOfBirth” column only accepts dates.
  • A “Price” column only accepts numeric values.

Strong typing also allows database engines to optimize storage and querying. For example:

  • Numbers can be indexed for fast lookup
  • Dates can be naturally compared and sorted

4. Easy Querying and Analysis

Because structured data adheres to a strict model, with the structure being fixed and known, it can be easily accessed and analyzed using query languages like SQL (Structured Query Language). SQL enables operations such as filtering, aggregating, joining data across tables, sorting, and more. It can be used to generate reports from the data quickly and consistently.

This is why structured data is ideal for business reporting, dashboards, and operational systems.

Database systems like Azure SQL Database use SQL to let users retrieve specific records and perform analytics efficiently.

As an example, a SQL query like the one below – which retrieves the name and hire date of employees who were hired after 01/01/2024 – is simple and efficient when run against structured data:

SELECT Name, HireDate
FROM Employees
WHERE HireDate > '2024-01-01';

5. Enforced Data Integrity and Rules

Relational databases that store structured data use rules and constraints to preserve data integrity, such as:

  • Primary keys to uniquely identify records
  • Foreign keys to express and enforce relationships between tables
  • Constraints like NOT NULL, UNIQUE, and CHECK, prevent invalid/unwanted data

These rules, along with the data typing, ensure data remains accurate, consistent, and meaningful across the entire dataset. Every row follows the same structure. This makes the data predictable, reliable and trustworthy for business reporting and analytics.

Because of this consistency:

  • Data validation is easier.
  • Automated processes function reliably.
  • Analytical and reporting tools deliver accurate results.

6. Indexing and Optimization

Although this is not a core feature, structured data systems often support indexing, which speeds up querying of data by creating optimized paths to specific values. This makes search and retrieval faster and is very important, and necessary in many cases, when working with large datasets.


Where Structured Data Is Used

Structured data is foundational in many classic applications, including:

  • Relational databases such as Azure SQL Database
    • Many business applications use SQL databases (from a variety of vendors, including Microsoft, Oracle, and others) to store data.
  • Data warehouses that aggregate business data for analytics
  • Spreadsheet systems like Microsoft Excel

All of these use fixed schemas and are typically queried with SQL or BI tools. In the Azure ecosystem, services like Azure SQL Database and Azure Synapse Analytics are designed to handle structured data workloads — enabling high-performance querying, transaction processing, and analytics.


Why Structured Data Matters for DP-900

Structured data forms the foundation of many business applications and analytical systems.

Understanding structured data is essential because:

  • It’s the foundation of relational data concepts on Azure.
  • It’s the baseline for SQL and transactional processing.
  • Many Azure services prioritize structured workloads for performance and reliability.

Understanding its features helps you:

✔ Know when to use relational databases versus non-relational stores
✔ Understand how schema affects querying and data integrity
✔ Recognize the strengths and limitations of structured formats in Azure environments

Being clear on how structured data is defined, stored, and queried will help you distinguish it from semi-structured and unstructured data — a key skill in the DP-900 exam.


Benefits of Structured Data

Because of its organization and predictability, structured data offers several advantages:

✔ Easy querying and reporting — supported directly by SQL.
✔ High data integrity — enforced through schemas and validation rules.
✔ Efficient storage and processing — optimized for performance.
✔ Readily usable by analytics tools — ideal for dashboards and BI.

These benefits make structured data ideal for many enterprise workloads where accuracy, speed, and reliability are essential.


Structured Data vs. Other Data Types

To further your understanding of structured data, it helps to contrast it with the other data types:

  • Semi-structured data has some organization but lacks a strict schema (e.g., JSON).
  • Unstructured data has no inherent structure (e.g., text documents, images).

Structured data lives on the most rigid end of this spectrum, which is why it’s easy to manage with traditional databases and analytics tools.


Summary: Exam-Relevant Takeaways

  • Structured data sits in rows and columns with a predefined schema.
    • ✔ Structured Data = predefined schema + tables + columns
  • Each column has a defined data type and validation rules.
    • ✔ Strong typing and consistency
  • Structured data can be queried efficiently with SQL.
    • ✔ Efficient querying with SQL
  • Its organization supports consistent, reliable, and fast analytics.
    • ✔ Enforced integrity via constraints and keys

Understanding these features will help you recognize when structured data is the right representation and how it compares to other data forms in Azure scenarios.


Go to the Practice Exam Questions for this topic.

Go to the DP-900 Exam Prep Hub main page.
Practice Questions: Describe features of structured data (DP-900 Exam Prep)

Practice Questions


Question 1

Which statement best describes structured data?

A. Data stored as images and videos
B. Data organized in key-value pairs without a schema
C. Data organized in rows and columns with a predefined schema
D. Data that can only be stored in files

✅ Answer: C

Explanation:
Structured data uses a fixed schema and is typically organized into tables with rows and columns, making it easy to query and analyze.


Question 2

Which of the following is a defining characteristic of structured data?

A. Schema-on-read
B. Schema-on-write
C. No enforced data types
D. Free-form text storage

✅ Answer: B

Explanation:
Structured data uses schema-on-write, meaning the structure (tables, columns, data types) must be defined before data is stored.


Question 3

You have a table with columns CustomerID, Name, and JoinDate. Each column has a defined data type. What feature of structured data does this demonstrate?

A. Indexing
B. Semi-structured storage
C. Strong data typing
D. Unstructured formatting

✅ Answer: C

Explanation:
Structured data enforces strong data typing, ensuring each column only accepts valid values (e.g., dates in date columns).


Question 4

Which language is most commonly used to query structured data?

A. Python
B. JSON
C. SQL
D. XML

✅ Answer: C

Explanation:
Structured data is designed to be queried using SQL (Structured Query Language).


Question 5

Which Azure service is primarily designed to store structured relational data?

A. Azure Blob Storage
B. Azure Data Lake Storage
C. Azure SQL Database
D. Azure File Storage

✅ Answer: C

Explanation:
Azure SQL Database is a managed relational database service optimized for structured data.


Question 6

What does a row represent in structured data?

A. A column definition
B. A schema
C. A single record or entity instance
D. A data type

✅ Answer: C

Explanation:
Each row represents one complete record (for example, one customer or one order).


Question 7

Which feature helps ensure that every record in a table can be uniquely identified?

A. Foreign key
B. Primary key
C. Index
D. View

✅ Answer: B

Explanation:
A primary key uniquely identifies each row and is a core integrity feature of structured data systems.


Question 8

Why is structured data well suited for reporting and dashboards?

A. It allows free-form documents
B. It does not require validation
C. It supports predictable schemas and efficient queries
D. It stores multimedia content

✅ Answer: C

Explanation:
Fixed schemas and SQL support make structured data ideal for analytics, reporting, and BI workloads.


Question 9

Which of the following best illustrates structured data?

A. A collection of photos
B. JSON log files
C. A spreadsheet with defined columns
D. Audio recordings

✅ Answer: C

Explanation:
Spreadsheets with consistent columns and rows are classic examples of structured data.


Question 10

What is a major benefit of enforcing constraints such as NOT NULL and UNIQUE?

A. Faster internet connections
B. Reduced storage costs
C. Improved data integrity
D. Automatic encryption

✅ Answer: C

Explanation:
Constraints help maintain accuracy and consistency, which is a key strength of structured data systems.


✅ Quick Exam Takeaway

For DP-900, remember:

  • Structured data uses tables (rows + columns)
  • Requires a predefined schema
  • Enforces data types and constraints
  • Is queried with SQL
  • Commonly lives in relational databases like Azure SQL Database

Go to the DP-900 Exam Prep Hub main page.

How to update the number format of the card visual in Power BI

Don’t pull your hair out … 😊

In more recent versions of Power BI, to change the display format of your measure in a card visual, do the following …

Click on the card visual. Then go the format pane (paintbrush), and the “Visual” tab within it.

Expand the “Callout” section.  Change the “Apply settings to” dropdown from “All” to the measure you want to change.

Scroll down, and change the “Display Units” parameter to your desired setting (“None” is also an option).

Optionally, if you do not already have the outcome you need from the above change, you can go to the “General” tab and make changes to the “Data format” parameters (such as decimal places, percentage, comma separator for thousands, etc) to get the exact number format that you want.

Good luck on your data journey!

How AI Is Changing Analytics (and How It Isn’t) — A Power BI and Modern Analytics Perspective

If you use Power BI or other modern data platforms today, you don’t have to look far to see AI everywhere:

  • Copilot inside Power BI and Fabric
  • Natural language Q&A visuals
  • Auto-generated DAX and measures
  • Smart narratives
  • Automated insights
  • Forecasting visuals
  • AutoML in Fabric
  • AI-assisted data prep

It may appear like analytics is becoming fully automated.

In reality, what’s happening is more nuanced.

AI is reshaping how analytics teams work — but it hasn’t replaced the fundamentals that actually make analytics valuable.

Let’s look at both sides through the lens of Power BI and today’s analytics stack.


How AI Is Changing Analytics

1. Power BI Is Becoming an “Analytics Co-Pilot”

With Copilot and built-in AI features, Power BI increasingly behaves like a smart assistant.

You can now:

  • Generate report pages from prompts
  • Create measures using natural language
  • Ask Copilot to explain DAX
  • Get auto-generated summaries of visuals
  • Build starter models and layouts

Instead of starting from a blank canvas, analysts can begin with a rough first draft produced by AI.

This doesn’t eliminate the need for modeling or design — but it dramatically reduces setup time.

The result: faster prototyping and quicker iteration.


2. Natural Language Q&A Is Expanding Self-Service Analytics

Power BI’s Q&A visual allows business users to type:

“Show total sales by region for last quarter.”

Power BI translates this into queries and visuals automatically.

This is part of a broader trend across platforms: conversational analytics.

Snowflake, Databricks, Fabric, and BI tools now all support some form of natural language interaction.

This lowers the barrier to entry for analytics and reduces dependency on data teams for simple questions.

However, this only works well when:

  • Tables are properly named
  • Relationships are correct
  • Measures are clearly defined

Which brings us back to fundamentals.


3. Built-In AI Makes Advanced Analytics Easier

Power BI and Fabric now include:

  • Forecasting visuals
  • Anomaly detection
  • AutoML models
  • Cognitive services
  • Predictive features

What once required data scientists can often be done directly inside the platform.

This enables analysts to:

  • Add predictions to reports
  • Detect unusual behavior
  • Cluster customers
  • Score records

All without building custom ML pipelines.

Advanced analytics is becoming part of everyday BI.


4. AI Is Improving Developer Productivity

For analytics professionals, AI has become a daily productivity tool:

  • Writing DAX measures
  • Generating SQL
  • Creating Power Query transformations
  • Explaining model errors
  • Drafting documentation

Instead of searching forums or writing everything from scratch, teams use AI to accelerate development.

This is especially powerful for:

  • Junior analysts learning faster
  • Senior engineers moving quicker
  • Teams standardizing patterns

AI acts as an always-available assistant.


How AI Isn’t Changing Analytics

Despite all of this, Power BI projects (and analytics project in general) still succeed or fail for the same reasons they always have.


1. Data Modeling Still Drives Everything

Copilot can generate visuals.

It cannot fix a broken model.

If your Power BI semantic model has:

  • Poor relationships
  • Ambiguous dimensions
  • Duplicate metrics
  • Inconsistent grain

Your reports will still be confusing — no matter how much AI you add.

Star schemas, clear measures, and well-designed semantic layers remain essential.

AI works on top of your model. It does not replace it.


2. Data Quality Still Determines Trust

AI-powered insights mean nothing if the data is wrong.

If, for example:

  • Sales numbers don’t match Finance
  • Customer definitions vary by report
  • Dates behave inconsistently

Users will stop trusting dashboards.

Modern platforms like Fabric emphasize data pipelines, lakehouses, governance, and lineage for a reason.

Analytics still starts with reliable data engineering.


3. Metrics Still Require Human Agreement

Power BI can calculate anything.

AI can suggest formulas.

But only people can agree on:

  • What “revenue” means
  • How churn is defined
  • Which KPIs matter
  • What targets are realistic

Metric alignment remains a business process, not a technical one.

No AI can resolve organizational ambiguity.


4. Dashboards Don’t Drive Action — People Do

Smart narratives and AI summaries are useful.

But decisions still depend on:

  • Context
  • Priorities
  • Risk tolerance
  • Strategy

A Power BI report becomes valuable only when someone uses it to change behavior.

That requires storytelling, persuasion, and leadership — not just algorithms.


What This Means for Power BI and Analytics Professionals

AI is changing the workflow, not the purpose of analytics.

Less time spent on:

  • Boilerplate DAX
  • First-pass visuals
  • Manual exploration

More time spent on:

  • Understanding business problems
  • Designing models
  • Interpreting results
  • Influencing decisions

The role evolves from “report builder” to:

  • Analytics translator
  • Business partner
  • Insight driver

Power BI professionals who thrive will combine:

  • Strong modeling skills
  • Business understanding
  • Communication
  • Strategic thinking
  • AI-assisted productivity

The Bottom Line

Power BI and modern analytics platforms are becoming AI-powered.

But analytics is not becoming automatic.

AI accelerates:

  • Report creation
  • Exploration
  • Advanced analytics
  • Developer productivity

It does not replace:

  • Data modeling
  • Data quality
  • Business context
  • Metric alignment
  • Human judgment

AI amplifies good analytics practices — and exposes bad ones faster.

Organizations that succeed will be the ones that invest in:

  • Solid data foundations
  • Clear semantic models
  • Skilled analytics teams
  • Thoughtful AI adoption

Not just shiny features.


Thanks for reading and good luck on your data journey!

Python Lists vs Dictionaries: Differences and uses

If you’re learning Python (or brushing up your fundamentals), two of the most important data structures you’ll encounter are lists and dictionaries.

They both store collections of data — but they solve very different problems.

Understanding when to use each will make you a better coder.

Let’s break it down.


What Is a Python List?

A list is an ordered collection of items.

You access elements by their position (index).

Example

fruits = ["apple", "banana", "orange"]
print(fruits[0]) # apple
print(fruits[1]) # banana

Key Characteristics

✅ Ordered
✅ Indexed by position (0, 1, 2…)
✅ Allows duplicates
✅ Mutable (you can change it)

Common Use Cases for Lists

Use a list when:

  • Order matters
  • You want to loop through items
  • You need to store duplicates
  • You mainly care about sequence

Examples:

scores = [85, 90, 78, 92]
names = ["Alice", "Bob", "Charlie"]
temperatures = [72.5, 73.1, 70.8]

What Is a Python Dictionary?

A dictionary stores data as key–value pairs.

Instead of using indexes, you access values by keys.

Example

person = {
"name": "Alice",
"age": 30,
"city": "Seattle"
}
print(person["name"]) # Alice

Key Characteristics

✅ Uses keys instead of indexes
✅ Extremely fast lookups
✅ Keys must be unique
✅ Values can be anything
✅ Mutable

Common Use Cases for Dictionaries

Use a dictionary when:

  • You need to label your data
  • You want fast lookups
  • You’re modeling real-world objects
  • You care about meaning, not position

Examples:

employee = {
"id": 123,
"department": "IT",
"salary": 85000
}
prices = {
"apple": 1.25,
"banana": 0.75,
"orange": 1.00
}

Core Difference (Conceptually)

Think of it this way:

  • Lists answer: “What is the 3rd item?”
  • Dictionaries answer: “What is the value for this key?”

That’s the fundamental distinction.


Practical Comparison

FeatureListDictionary
Access methodIndexKey
Order mattersYesYes (Python 3.7+)
Lookup speedSlower for searchesVery fast
Duplicates allowedYesKeys: No
Best forSequencesLabeled data

Code Examples: Same Data, Different Structures

Using a List

users = ["Alice", "Bob", "Charlie"]
for user in users:
print(user)

Here, we just care about iterating in order.


Using a Dictionary

users = {
"user1": "Alice",
"user2": "Bob",
"user3": "Charlie"
}
print(users["user2"]) # Bob

Now we care about identifying users by keys.


Performance Considerations

Searching a List

if "banana" in fruits:
print("Found!")

Python may need to check many elements.


Searching a Dictionary

if "banana" in prices:
print("Found!")

This is nearly instant, even with huge dictionaries.

Note: Dictionaries are optimized for fast key-based lookups.


Advantages and Disadvantages

Lists

Advantages

  • Simple and intuitive
  • Preserves order naturally
  • Great for iteration
  • Supports slicing

Disadvantages

  • Slow lookups for large lists
  • No built-in labels for elements

Dictionaries

Advantages

  • Lightning-fast access by key
  • Self-documenting structure
  • Ideal for structured data
  • Easy to model objects

Disadvantages

  • Slightly more memory overhead
  • Keys must be unique
  • Less natural for purely ordered data

When Should You Use Each?

Use a List when:

  • You have a collection of similar items
  • Order matters
  • You’ll mostly loop through values
  • You don’t need named fields

Example:

daily_sales = [120, 150, 130, 160]

Use a Dictionary when:

  • Each value has meaning
  • You need fast access
  • You’re representing entities
  • You want readable code

Example:

customer = {
"name": "John",
"email": "john@example.com",
"active": True
}

Real-World Analogy

List

Like a grocery list:

  1. Milk
  2. Eggs
  3. Bread

Position matters.

Dictionary

Like a contact card:

Name → Sarah
Phone → 555-1234
Email → sarah@email.com

Each field has a label.


They’re Often Used Together

In real projects, you’ll usually combine both:

customers = [
{"name": "Alice", "age": 30},
{"name": "Bob", "age": 25},
{"name": "Charlie", "age": 35}
]

A list of dictionaries is one of the most common patterns in Python and data work.


Final Thoughts

  • Lists are best for ordered collections.
  • Dictionaries are best for labeled data and fast lookups.
  • Choosing the right one makes your code cleaner, clearer, and more efficient.

Mastering these two structures is a major step toward becoming confident in Python — and they form the backbone of almost every data-driven application.


Thanks for reading and good luck on your data journey!

How to delete multiple fields (including measures) at the same time in Power BI

You find that you need to delete many fields (which can include measures) from a Power BI model / project, such as after removing a part of the solution that is no longer needed or will not be a part of the current release.

From the “Report View”, you can delete only one field at a time. However, you can delete multiple at a time from the “Model View”.

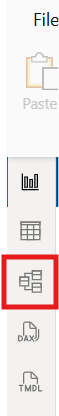
In your Power BI report, click the “Model View” in the left navigation pane.

Then, in the Data pane on the right, hold down the Ctrl key and click on each of the field that you want to delete.

All the fields you clicked on will be “selected” and you should see that they are.

Then, click the Delete key -or- right-click the fields and select “Delete from model”.

A “Delete items” confirmation dialog will pop up. After confirming that you have selected the fields you really want to delete, click “Yes”, or click “Cancel” to cancel your action.

Good luck!

Microsoft Fabric & Power BI Glossary (100 Terms)

Below is a table of 100 “Microsoft Fabric and Power BI” terms and definitions, sorted alphabetically (except for the first two entries). You can use it as a reference to get a quick idea of what something is or means, and also as a way to identify topics to research.

#TermDefinition & Example
1Microsoft FabricUnified analytics platform combining data engineering, warehousing, science, and BI. Example: Building pipelines and dashboards in one workspace.
2Power BIMicrosoft’s business intelligence visualization tool. Example: Sales dashboards.
3AggregationsPre-summarized tables. Example: Faster queries.
4Anomaly DetectionHighlights unusual values. Example: Sales spike.
5AppPackaged Power BI content. Example: Sales app.
6BookmarksSaved report states. Example: Guided navigation.
Article on configuring bookmarks
7Bronze LayerRaw data. Example: Ingested CSVs.
8Calculated ColumnStatic DAX column. Example: Profit category.
9Calculation GroupReusable DAX logic. Example: Time intelligence.
10Capacity Metrics AppPerformance insights. Example: CU spikes.
11Capacity Unit (CU)Measure of Fabric compute. Example: Performance scaling.
12Certified DatasetOfficial data source. Example: Finance semantic model.
13Composite ModelMix of Import + DirectQuery. Example: Hybrid datasets.
Article about designing and building composite models
14Composite TableMixed storage table. Example: Hybrid dimensions.
15Custom VisualMarketplace visuals. Example: Sankey diagram.
16DashboardKPI overview page. Example: Executive metrics.
17Data CatalogDiscover datasets. Example: Search semantic models.
18Data LineageShows data flow. Example: Source → report.
19Data MartSelf-service warehouse. Example: Analyst-owned SQL.
20Data Model SizeMemory footprint. Example: Import limits.
21Data PipelineOrchestrates data movement. Example: Copy from S3.
22Data Source CredentialsAuthentication info. Example: SQL login.
23Data WarehouseStructured analytical database. Example: T-SQL querying sales facts.
24Dataflow Gen2Fabric ETL artifact. Example: Cloud ingestion pipelines.
25DAXFormula language for measures. Example: Total Sales calculation.
26Delta LakeTransactional file format. Example: ACID parquet.
27Deployment PipelineDev/Test/Prod promotion. Example: CI/CD.
Article on creating and configuring deployment pipelines
28Dimension TableDescriptive attributes. Example: Products.
Article that describes fact and dimension tables and how to create them
29Direct LakeQueries OneLake directly without import. Example: Near real-time reporting.
30DirectQueryQueries source system live. Example: SQL Server reporting.
Article on choosing between DirectQuery and Import in Power BI
31Drill DownNavigate deeper. Example: Year → Month.
Article on Power BI drilldown vs drill-through
32Drill ThroughJump to detail page. Example: Customer profile.
Article on Power BI drilldown vs drill-through
33Embedded AnalyticsPower BI in apps. Example: Web portals.
34EndorsementCertified or promoted datasets. Example: Trusted models.
35End-to-End AnalyticsFull Fabric workflow. Example: Ingest → model → report.
36Fabric CapacityCompute resources. Example: F64 SKU.
37Fabric CI/CDAutomated deployments. Example: Pipeline promotion.
38Fabric Data ActivatorEvent-based alerts. Example: Trigger email on anomaly.
39Fabric ItemAny asset. Example: Notebook, warehouse.
40Fabric Monitoring HubCapacity tracking. Example: CU consumption.
41Fabric WorkspaceContainer for Fabric assets. Example: Lakehouse + reports together.
42Fact TableStores measurable events. Example: Orders.
Article that describes fact and dimension tables and how to create them
43GatewayConnects on-prem data. Example: Local SQL Server.
44Git IntegrationSource control. Example: Azure DevOps.
45GoalsPerformance targets. Example: Revenue quota.
46Gold LayerBusiness-ready data. Example: KPI models.
47Import ModeData loaded into Power BI memory. Example: Daily refresh model.
48Incremental RefreshOnly refresh recent data. Example: Last 30 days.
49LakehouseCombines data lake + warehouse features. Example: Spark + SQL analytics.
50Lineage ViewDependency visualization. Example: Pipeline flow.
51M LanguageLanguage behind Power Query. Example: Transform steps.
52MeasureDynamic DAX calculation. Example: YTD Revenue.
53Medallion ArchitectureBronze/Silver/Gold layers. Example: Curated analytics.
54Metrics AppGoal tracking. Example: OKRs.
55Microsoft PurviewGovernance integration. Example: Catalog assets.
56MirroringReplicates operational DBs. Example: Azure SQL sync.
57Model Refresh FailureUpdate error. Example: Credential expired.
58Model ViewRelationship design canvas. Example: Schema building.
59NotebookSpark coding environment. Example: PySpark transformations.
60Object-Level SecurityHides tables/columns. Example: HR salary masking.
61OneLakeFabric’s centralized data lake. Example: Shared parquet storage.
62Page-Level FilterApplies to page. Example: Region filter.
63Paginated ReportPixel-perfect reporting. Example: Invoice PDFs.
64Performance AnalyzerMeasures visual speed. Example: DAX tuning.
65PerspectiveUser-specific model view. Example: Finance vs Sales.
66Power BI DesktopAuthoring tool. Example: Local report creation.
67Power BI ServiceCloud hosting platform. Example: app.powerbi.com.
68Power QueryETL engine in Power BI/Fabric. Example: Cleaning CSV files.
69Preview FeatureEarly-access capability. Example: New visuals.
70PySparkPython Spark API. Example: Transform big data.
71Query FoldingPushes logic to source. Example: SQL filtering.
72RefreshUpdating model data. Example: Nightly refresh.
73RelationshipLink between tables. Example: CustomerID join.
74ReportCollection of visuals. Example: Finance report.
75Report-Level FilterApplies everywhere. Example: Fiscal year.
76REST APIAutomates Power BI. Example: Dataset refresh trigger.
77Row-Level Security (RLS)Restricts data by user. Example: Region access.
Articles on implementing RLS roles and configuring RLS group membership
78Semantic ModelLogical layer for reporting (formerly dataset). Example: Measures and relationships.
79Sensitivity LabelData classification. Example: Confidential.
Article on applying sensitivity labels
80ShareGrant report access. Example: Email link.
81ShortcutVirtual data reference. Example: External ADLS folder.
82Silver LayerCleaned data. Example: Standardized tables.
83SlicerInteractive filter. Example: Year selector.
84SparkDistributed compute engine. Example: Large joins.
85SQL Analytics EndpointT-SQL interface to Lakehouse. Example: BI queries.
86Star SchemaFact table with dimensions. Example: Sales model.
87SubscribeScheduled email snapshots. Example: Weekly KPIs.
88Tabular EditorExternal modeling tool. Example: Bulk measures.
89Tenant SettingAdmin control. Example: Export permissions.
90ThemesStyling reports. Example: Brand colors.
91TooltipHover info. Example: Exact sales value.
Article on creating tooltips in Power BI
92T-SQLSQL dialect in Fabric. Example: SELECT statements.
93Usage MetricsReport adoption stats. Example: View counts.
94VisualChart or table. Example: Bar chart.
95Visual InteractionCross-filtering visuals. Example: Click bar filters table.
96Visual-Level FilterApplies to one visual. Example: Top 10 only.
97Warehouse EndpointSQL access to Lakehouse. Example: SSMS connection.
98Workspace App AudienceTargeted content. Example: Exec vs Sales.
99Workspace RoleAccess level. Example: Viewer, Member.
100XMLA EndpointAdvanced model management. Example: Tabular Editor.

Thanks for reading!

Understanding the Different Types / Categories / Classifications of Data (Explained Simply)

Data is the foundation of every analytics, AI, and business intelligence initiative. Yet one of the most common sources of confusion—especially for people new to data—is that “data types” or “data classifications” or “data categories” doesn’t mean just one thing.

In reality, data can be classified in several different ways at once, depending on:

  • How it’s structured
  • What it represents
  • How it’s measured
  • How it behaves over time
  • Who owns it
  • How it’s used

A single dataset can belong to multiple categories simultaneously.

Let’s take a look at some of the important dimensions of data classification.

Dimensions of Data Classification


1. Data by Structure

This describes how organized the data is and how easily it fits into traditional databases.

Structured Data

Highly organized data with a fixed schema (rows and columns).

Examples

  • Sales tables
  • Customer records
  • Financial transactions

Common storage

  • Relational databases (SQL Server, PostgreSQL, MySQL)
  • Data warehouses

Key characteristics

  • Easy to query
  • Strong typing
  • Ideal for reporting and dashboards

Semi-Structured Data

Doesn’t follow rigid tables, but still contains identifiable structure.

Examples

  • JSON
  • XML
  • Parquet
  • Avro
  • Log files

Key characteristics

  • Flexible schema
  • Common in modern cloud systems and APIs
  • Often used in data lakes

Unstructured Data

No predefined structure.

Examples

  • Text documents
  • Emails
  • Images
  • Audio
  • Video
  • Social media posts

Key characteristics

  • Harder to analyze directly
  • Often requires AI or NLP
  • Represents the majority of enterprise data volume today

2. Data by Nature or Meaning

This focuses on what the data represents.

Qualitative Data

Descriptive, non-numeric data.

Examples

  • Product reviews
  • Customer feedback
  • Colors
  • Categories

Used heavily in:

  • Sentiment analysis
  • User research
  • Text analytics

Quantitative Data

Numeric data that can be measured or counted.

Examples

  • Revenue
  • Temperature
  • Page views
  • Age

Forms the backbone of:

  • Analytics
  • Statistics
  • Machine learning

3. Categorical vs Numerical Data

A more analytical lens commonly used in statistics and ML.

Categorical Data

Represents groups or labels.

Nominal Data

Categories with no natural order.

Examples

  • Country
  • Product type
  • Gender

Ordinal Data

Categories with a meaningful order.

Examples

  • Satisfaction levels (Low → Medium → High)
  • Education level
  • Star ratings

Important note: although ordered, the distance between values is unknown.


Numerical Data

Actual numbers.

Discrete Data

Countable values.

Examples

  • Number of customers
  • Items sold
  • Defects per batch

Continuous Data

Measured values on a scale.

Examples

  • Height
  • Weight
  • Temperature
  • Time duration

4. Levels of Measurement

This classification comes from statistics and helps determine which calculations are valid.

Nominal

Just labels.


Ordinal

Ordered labels.


Interval

Numeric data with consistent spacing but no true zero.

Examples

  • Celsius temperature
  • Calendar dates

You can add and subtract, but ratios don’t make sense.


Ratio

Numeric data with a true zero.

Examples

  • Revenue
  • Distance
  • Time spent
  • Quantity

Supports all mathematical operations.


5. Data by Time

How data behaves over time is critical for analytics.

Time Series Data

Measurements captured at regular intervals.

Examples

  • Stock prices
  • Website traffic per day
  • Sensor readings

Used heavily in:

  • Forecasting
  • Trend analysis
  • Anomaly detection

Cross-Sectional Data

Snapshot at a single point in time.

Example

  • Customer demographics today

Panel (Longitudinal) Data

Tracks the same entities over time.

Example

  • Monthly sales by customer over several years

6. Data by Ownership and Sensitivity

Who controls the data — and how it must be protected.

Public Data

Freely available.

Examples

  • Government datasets
  • Open research data
  • Public APIs

Private Data

Owned by organizations or individuals.

Includes:

  • Customer records
  • Internal financials
  • Proprietary business data

Personally Identifiable Information (PII)

A critical subset of private data.

Examples

  • Name
  • Email
  • Phone number
  • SSN

Requires strict governance and compliance.


Sensitive / Confidential Data

High-risk data.

Examples

  • Medical records
  • Financial details
  • Authentication credentials

Protected by regulations such as GDPR, HIPAA, and CCPA.


7. Data by Source

Where the data comes from.

First-Party Data

Collected directly by your organization.


Second-Party Data

Shared by trusted partners.


Third-Party Data

Purchased or obtained externally.


8. Operational vs Analytical Data

An important architectural distinction.

Operational Data

Supports daily business activities.

Examples

  • Orders
  • Payments
  • Inventory

Lives in transactional systems.


Analytical Data

Optimized for reporting and insights.

Examples

  • Aggregated sales
  • Historical trends
  • KPI metrics

Lives in warehouses and lakes.


9. Other Important Modern Categories

Streaming / Real-Time Data

Generated continuously.

Examples

  • IoT sensors
  • Clickstreams
  • Event telemetry

Metadata

Data about data.

Examples

  • Column definitions
  • Data lineage
  • Refresh timestamps

Master Data

Core business entities.

Examples

  • Customers
  • Products
  • Employees

Reference Data

Standardized lookup values.

Examples

  • Country codes
  • Currency codes
  • Status lists

Bringing It All Together

A single dataset can belong to many categories at once. There is no “one” way to classify data.

For example, a Customer Purchase table might be structured, quantitative, ratio-based, time-series, private, operational, and first-party data — all at the same time.

Understanding these dimensions helps you:

  • Choose the right storage platform
  • Apply correct statistical methods
  • Design better models
  • Enforce governance and security
  • Build more effective analytics solutions
  • Choose the right visualizations
  • Engage is conversations about data and data projects with others at any level

Think of data types or classifications as “layers of perspective” — structure, meaning, measurement, time, ownership, and usage — each revealing something different about how your data should be handled and analyzed.

Mastering these foundations makes everything else in data—analytics, engineering, visualization, and AI—far more intuitive.


Thanks for reading and good luck on your data journey!

AI-900: Microsoft Azure AI Fundamentals certification exam Frequently Asked Questions (FAQs)

Below are some commonly asked questions about the AI-900: Microsoft Azure AI Fundamentals certification exam. Upon successfully passing this exam, you earn the Microsoft Certified: Azure AI Fundamentals certification.


What is the AI-900 certification exam?

The AI-900: Microsoft Azure AI Fundamentals exam validates your foundational knowledge of artificial intelligence (AI) concepts and how AI workloads are implemented using Microsoft Azure services.

Candidates who pass the exam demonstrate understanding of:

  • Core AI concepts and terminology
  • Machine learning workloads and Azure Machine Learning
  • Computer vision workloads using Azure AI Vision
  • Natural language processing workloads using Azure AI Language
  • Conversational AI workloads using Azure AI Bot Service and Azure AI Studio

This certification is designed for individuals who want to understand AI fundamentals and how Azure supports common AI scenarios. Upon successfully passing this exam, candidates earn the Microsoft Certified: Azure AI Fundamentals certification.


Is the AI-900 certification exam worth it?

The short answer is “yes“.

AI-900 is an excellent entry point into artificial intelligence and Microsoft’s AI ecosystem. Preparing for this exam helps you:

  • Build foundational AI literacy
  • Understand common AI workloads and use cases
  • Learn how Azure delivers AI services
  • Gain confidence discussing AI concepts with technical and business teams
  • Prepare for more advanced certifications such as AI-102, DP-100, or PL-300

For beginners, students, business professionals, and technologists new to AI, AI-900 provides structured learning and practical context without requiring deep programming experience.


How many questions are on the AI-900 exam?

The AI-900 exam typically contains between 40 and 60 questions.

Question formats may include:

  • Single-choice and multiple-choice questions
  • Multi-select questions
  • Drag-and-drop or matching questions
  • Short scenario-based questions

The exact number and format can vary slightly from exam to exam.


How hard is the AI-900 exam?

AI-900 is considered a fundamentals-level exam and is generally approachable for beginners.

The challenge comes from:

  • Learning AI terminology and concepts
  • Understanding when to use different Azure AI services
  • Interpreting scenario-based questions
  • Distinguishing between machine learning, computer vision, NLP, and conversational AI workloads

With focused preparation, most candidates find the exam very achievable.

Helpful preparation resources include:


How much does the AI-900 certification exam cost?

As of early 2026, the standard exam pricing is approximately:

  • United States: $99 USD
  • Other countries: Regionally adjusted pricing applies

Microsoft occasionally offers student discounts, academic pricing, and exam vouchers, so it’s worth checking the official Microsoft certification site before scheduling your exam.


How do I prepare for the Microsoft AI-900 certification exam?

The most important advice is not to rush. Sit for the exam only after you have fully prepared.

Recommended preparation steps:

  1. Review the official AI-900 exam skills outline.
  2. Complete the free Microsoft Learn AI-900 learning path.
  3. Study core AI concepts such as classification, regression, clustering, and responsible AI.
  4. Learn the purpose of key Azure AI services (Azure Machine Learning, Azure AI Vision, Azure AI Language, Azure AI Bot Service).
  5. Take practice exams to confirm your readiness.

Additional learning resources include:

Hands-on labs are helpful but not strictly required. Conceptual understanding is the primary focus for the AI-900.


How do I pass the AI-900 exam?

To maximize your chances of passing:

  • Focus on understanding concepts rather than memorization
  • Learn what each Azure AI service is designed for
  • Carefully read scenario questions before answering
  • Eliminate obviously incorrect choices
  • Manage your time effectively

Consistently performing well on reputable practice exams is usually a good indicator that you’re ready.


What is the best site for AI-900 certification dumps?

Using exam dumps is not recommended and may violate Microsoft’s exam policies.

Instead, rely on legitimate preparation resources such as:

  • Microsoft’s official practice exam, which can be accessed from the main certification page
  • High-quality community-created practice tests, such as those available at The Data Community’s AI-900 Exam Prep Hub
  • Scenario-based questions that reinforce understanding

Look beyond the exam. Legitimate preparation builds real skills that extend beyond the exam.


How long should I study for the AI-900 exam?

Study time varies based on background.

General guidelines:

  • Prior AI or Azure experience: 2–4 weeks
  • Some technical background: 3–5 weeks
  • Beginners or career switchers: 4–8 weeks

However, rather than focusing strictly on time, aim to understand all exam topics and perform well on practice tests before scheduling.


Where can I find training or a course for the AI-900 exam?

Training options include:

  • Microsoft Learn: Free, official learning path
  • Online platforms: Udemy, Coursera, and similar providers
  • YouTube: Free AI-900 playlists and walkthroughs
  • Subscription platforms: Datacamp and others offering AI fundamentals
  • Microsoft partners: Instructor-led courses
  • Community contributors: Free exam prep hub at The Data Community

A mix of structured learning and light hands-on exploration works well. While it’s totally fine to use any resources you find suitable based on your situation, you can most likely learn the required content and pass this exam using only “free” resources.


What skills should I have before taking the AI-900 exam?

Before attempting the exam, it helps to understand:

  • Basic computer concepts
  • Simple data concepts
  • High-level AI terminology
  • General cloud computing ideas

No programming experience is required.

AI-900 is designed specifically for beginners.


What score do I need to pass the AI-900 exam?

Microsoft exams are scored on a scale of 1–1000, and a score of 700 or higher is required to pass.

Scores are scaled based on question difficulty, not simply percentage correct.


How long is the AI-900 exam?

You are given approximately 60 minutes to complete the exam, not including onboarding and instructions.

Time pressure is generally lower than associate-level exams.


How long is the AI-900 certification valid?

The Microsoft Certified: Azure AI Fundamentals certification does not expire.

Unlike associate-level certifications, AI-900 currently does not require renewal.


Is AI-900 suitable for beginners?

Yes — AI-900 is specifically designed for beginners.

It’s ideal for:

  • Students
  • Career switchers
  • Business professionals exploring AI
  • Cloud beginners
  • Technical professionals new to artificial intelligence

No prior AI or Azure experience is required.


What roles benefit most from the AI-900 certification?

AI-900 is especially valuable for:

It also serves as a strong foundation before pursuing AI-102, DP-100, DP-203, or PL-300.


What languages is the AI-900 exam offered in?

The AI-900 certification exam is commonly offered in:

English, Japanese, Chinese (Simplified), Korean, German, French, Spanish, Portuguese (Brazil), Chinese (Traditional), Italian

Availability may vary by region.


Have additional questions? Post them in the comments.

Thanks for reading and good luck on your data journey!

AI in the Automotive Industry: How Artificial Intelligence Is Transforming Mobility

“AI in …” series

Artificial Intelligence (AI) is no longer a futuristic concept in the automotive world — it’s already embedded across nearly every part of the industry. From how vehicles are designed and manufactured, to how they’re driven, maintained, sold, and supported, AI is fundamentally reshaping vehicular mobility.

What makes automotive especially interesting is that it combines physical systems, massive data volumes, real-time decision making, and human safety. Few industries, such as healthcare, place higher demands on AI accuracy, reliability, and scale.

Let’s walk through how AI is being applied across the automotive value chain — and why it matters.


1. AI in Vehicle Design and Engineering

Before a single car reaches the road, AI is already at work.

Generative Design

Automakers use AI-driven generative design tools to explore thousands of design variations automatically. Engineers specify constraints like:

  • Weight
  • Strength
  • Material type
  • Cost

The AI proposes optimized designs that humans might never consider — often producing lighter, stronger components.

Business value:

  • Faster design cycles
  • Reduced material usage
  • Improved fuel efficiency or battery range
  • Lower production costs

For example, manufacturers now design lightweight structural parts for EVs using AI, helping extend driving range without compromising safety.

Simulation and Virtual Testing

AI accelerates crash simulations, aerodynamics modeling, and thermal analysis by learning from historical test data. Instead of running every scenario physically (which is expensive and slow), AI predicts outcomes digitally — cutting months from development timelines.


2. Autonomous Driving and Advanced Driver Assistance Systems (ADAS)

This is the most visible application of AI in automotive.

Modern vehicles increasingly rely on AI to understand their surroundings and assist — or fully replace — human drivers.

Perception: Seeing the World

Self-driving systems combine data from:

  • Cameras
  • Radar
  • LiDAR
  • Ultrasonic sensors

AI models interpret this data to identify:

  • Vehicles
  • Pedestrians
  • Lane markings
  • Traffic signs
  • Road conditions

Computer vision and deep learning allow cars to “see” in real time.

Decision Making and Control

Once the environment is understood, AI determines:

  • When to brake
  • When to accelerate
  • How to steer
  • How to merge
  • How to respond to unexpected obstacles

This requires millisecond-level decisions with safety-critical consequences.

ADAS Today

Even if full autonomy is still evolving, AI already powers features such as:

  • Adaptive cruise control
  • Lane-keeping assist
  • Automatic emergency braking
  • Blind-spot monitoring
  • Parking assistance

These systems are quietly reducing accidents and saving lives every day.


3. Predictive Maintenance and Vehicle Health Monitoring

Traditionally, vehicles were serviced on fixed schedules or after something broke.

AI enables a shift toward predictive maintenance.

How It Works

Vehicles continuously generate data from hundreds of sensors:

  • Engine performance
  • Battery health
  • Brake wear
  • Tire pressure
  • Temperature fluctuations

AI models analyze patterns across millions of vehicles to detect early signs of failure.

Instead of reacting to breakdowns, manufacturers and fleet operators can:

  • Predict component failures
  • Schedule maintenance proactively
  • Reduce downtime
  • Lower repair costs

For commercial fleets, this translates directly into operational savings and improved reliability.


4. Smart Manufacturing and Quality Control

Automotive factories are becoming AI-powered production ecosystems.

Computer Vision for Quality Inspection

High-resolution cameras combined with AI inspect parts and assemblies in real time, identifying:

  • Surface defects
  • Misalignments
  • Missing components
  • Paint imperfections

This replaces manual inspection while improving consistency and accuracy.

Robotics and Process Optimization

AI coordinates robotic arms, assembly lines, and material flow to:

  • Optimize production speed
  • Reduce waste
  • Balance workloads
  • Detect bottlenecks

Manufacturers also use AI to forecast demand and dynamically adjust production volumes.

The result: leaner factories, higher quality, and faster delivery.


5. AI in Supply Chain and Logistics

The automotive supply chain is incredibly complex, involving thousands of suppliers worldwide.

AI helps manage this complexity by:

  • Forecasting parts demand
  • Optimizing inventory levels
  • Predicting shipping delays
  • Identifying supplier risks
  • Optimizing transportation routes

During recent global disruptions, companies using AI-driven supply chain analytics recovered faster by anticipating shortages and rerouting sourcing strategies.


6. Personalized In-Car Experiences

Modern vehicles increasingly resemble connected smart devices.

AI enhances the driver and passenger experience through personalization:

  • Voice assistants for navigation and climate control
  • Adaptive seating and mirror positions
  • Personalized infotainment recommendations
  • Driver behavior analysis for comfort and safety

Some systems learn individual driving styles and adjust throttle response, braking sensitivity, and steering feel accordingly.

Over time, your car begins to feel uniquely “yours.”


7. Sales, Marketing, and Customer Engagement

AI doesn’t stop at manufacturing — it also transforms how vehicles are sold and supported.

Smarter Marketing

Automakers use AI to analyze customer data and predict:

  • Which models buyers are likely to prefer
  • Optimal pricing strategies
  • Best timing for promotions

Virtual Assistants and Chatbots

Dealerships and manufacturers deploy AI chatbots to handle:

  • Vehicle inquiries
  • Test-drive scheduling
  • Financing questions
  • Service appointments

This improves customer experience while reducing operational costs.


8. Electric Vehicles and Energy Optimization

As EV adoption grows, AI plays a critical role in managing batteries and energy consumption.

Battery Management Systems

AI optimizes:

  • Charging patterns
  • Thermal regulation
  • Battery degradation prediction
  • Range estimation

These models extend battery life and provide more accurate driving-range forecasts — two key concerns for EV owners.

Smart Charging

AI integrates vehicles with power grids, enabling:

  • Off-peak charging
  • Load balancing
  • Renewable energy optimization

This supports both drivers and utilities.


Challenges and Considerations

Despite rapid progress, significant challenges remain:

Safety and Trust

AI-driven vehicles must achieve near-perfect reliability. Even rare failures can undermine public confidence.

Data Privacy

Connected cars generate massive amounts of personal and location data, raising privacy concerns.

Regulation

Governments worldwide are still defining frameworks for autonomous driving liability and certification.

Ethical Decision Making

Self-driving systems introduce complex moral questions around accident scenarios and responsibility.


The Road Ahead

AI is transforming automobiles from mechanical machines into intelligent, connected platforms.

In the coming years, we’ll see:

  • Increasing autonomy
  • Deeper personalization
  • Fully digital vehicle ecosystems
  • Seamless integration with smart cities
  • AI-driven mobility services replacing traditional ownership models

The automotive industry is evolving into a software-first, data-driven business — and AI is the engine powering that transformation.


Final Thoughts

AI in automotive isn’t just about self-driving cars. It’s about smarter design, safer roads, efficient factories, predictive maintenance, personalized experiences, and sustainable mobility.

Much like how “AI in Gaming” is reshaping player experiences and development pipelines, “AI in Automotive” is redefining how vehicles are created and how people move through the world.

We’re witnessing the birth of intelligent transportation — and this journey is only just beginning.

Thanks for reading and good luck on your data journey!